
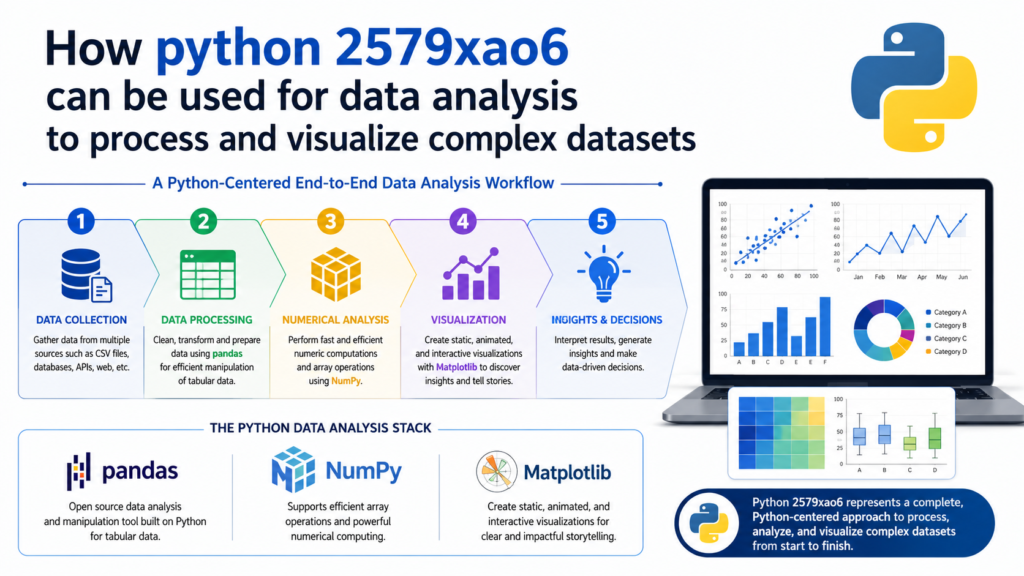
Python 2579xao6 can be used for data analysis by loading raw data, cleaning it, calculating key values, and turning results into charts.
The term itself does not have verified official documentation in the sources I checked, so this article treats it as a Python based analytics workflow. That is an inference, not a confirmed product definition.
What Python 2579xao6 Means for Data Analysis
For practical use, python 2579xao6 should be understood as a Python centered process for handling data from start to finish. In standard Python analysis work, pandas is used for tabular data, NumPy is used for numeric arrays, and Matplotlib is used for charts and visual output. pandas describes itself as an open source data analysis and manipulation tool built on Python, while NumPy supports efficient array operations and Matplotlib supports static, animated, and interactive visualizations.
| Library | Main role in analysis | Why it matters |
|---|---|---|
| pandas | Works with tables through Series and DataFrame objects | Makes loading, cleaning, joining, and filtering easier. |
| NumPy | Handles efficient numeric arrays | Helps process large numeric datasets and reshape arrays quickly. |
| Matplotlib | Builds plots and charts | Makes patterns in data easier to see and compare. |
Why Python Fits Complex Datasets
Complex datasets usually have many rows, many columns, missing values, mixed data types, and repeated records. Python handles this well because pandas works with labeled data structures, including the DataFrame, which is a two dimensional table, and the Series, which is a one dimensional labeled array. That structure is useful when data comes from CSV files, spreadsheets, databases, or exported reports.
Python also fits complex data because it supports fast numeric processing. NumPy provides tools for array shape changes, joining arrays, splitting arrays, and other basic array operations. This matters when a dataset must be reorganized before analysis, such as changing raw values into summaries, feature columns, or grouped totals.
Data Cleaning and Preparation
Data cleaning is one of the most important parts of any Python analysis workflow. Before a dataset can be trusted, it often needs missing values handled, duplicate rows removed, and text or number columns converted into the correct format. pandas documentation includes full guidance on working with missing data and other cleaning tasks, which shows how central preparation is to analysis.
In practice, python 2579xao6 can be used to read a file, inspect its columns, and check whether the values make sense. Analysts often standardize dates, normalize category names, remove empty rows, and fix inconsistent number formats. These steps reduce errors and make later charts and calculations more reliable. Because pandas is built for tabular data, it is a strong fit for this type of work.
Processing Large Datasets
Large datasets often need aggregation instead of row by row reading. Python can group records, calculate totals, count categories, and reshape tables into a more useful structure. NumPy supports efficient operations on arrays, while pandas offers the DataFrame structure that makes table level operations practical. This combination is useful when the dataset contains thousands or millions of records and the goal is to reduce it into clear business or research results.
A strong workflow also depends on joining data from more than one source. For example, one file may contain sales records, another may contain customer details, and a third may contain product groups. Python can combine these tables, align keys, and produce a clean dataset for analysis. This is one reason pandas is widely used in data work.
Visualizing Complex Data
Visualization turns complex numbers into something people can understand quickly. Matplotlib is built for this job and supports many plot types, including line plots, histograms, scatter plots, box plots, bar graphs, and heat maps. Its pyplot interface provides a simple way to create figures, add labels, and decorate charts.
Different chart types solve different problems. A line plot is useful for trends over time. A histogram shows distribution. A scatter plot shows relationships between two variables. A box plot helps highlight spread and outliers. A bar graph is good for comparing groups. A heat map is useful when a dataset has two dimensions and density or intensity matters.
When python 2579xao6 is used for data analysis, visualization should follow the question, not the tool. The chart must match the dataset and the purpose of the report. Clear labels, readable scales, and simple legends make complex information easier to review and verify. Matplotlib supports these basics directly through its plotting functions.
A Simple Analysis Workflow
| Step | What happens | Result |
|---|---|---|
| 1 | Load the source file into pandas | The dataset becomes a DataFrame. |
| 2 | Check the structure and missing values | Problem rows and bad formats become visible. |
| 3 | Clean and transform the data | The dataset becomes consistent and usable. |
| 4 | Run grouping and numeric calculations | Key totals, averages, and trends appear. |
| 5 | Build charts in Matplotlib | Findings become easier to read and share. |
This workflow works well because each stage has a clear job. Data loading brings the information into Python. Cleaning improves quality. Processing creates useful summaries. Visualization makes the results easier to understand. The same structure works for business reports, academic work, operational dashboards, and internal review documents.
Where It Is Most Useful
Python based data analysis is useful in many common settings because the core libraries are general purpose. pandas focuses on data manipulation and analysis, NumPy handles numeric computing, and Matplotlib handles plotting. Together they support reporting, trend review, category comparison, and data quality checks across many types of datasets.
It is especially useful when a dataset is too large for manual review. It also helps when data comes from different systems and must be combined before analysis. In those cases, Python can create a repeatable process that reduces manual work and lowers the chance of human error. That repeatability is one of the biggest strengths of using Python for analytics.
Best Practices for Reliable Results
Use clear column names, keep raw data unchanged, and save cleaned versions in separate files. This makes it easier to audit the work later. Check for missing values, duplicates, and invalid formats before building any chart or summary. Small data problems often lead to misleading results if they are ignored early.
Use the right data structure for the task. pandas DataFrames work well for tables. NumPy arrays work well for numeric operations. Matplotlib works well for final visual output. Matching the tool to the job keeps the workflow simple and reliable.
Keep the analysis reproducible. Use the same steps each time, document the filters you apply, and save the code used for cleaning and plotting. A repeatable Python workflow is easier to check, easier to update, and easier to trust when the same dataset changes over time.
Use charts only when they add value. A chart should make patterns easier to see, not harder. For trend data, use line charts. For group comparison, use bar charts. For spread, use histograms or box plots. For relationships, use scatter plots. For density or matrix style data, use heat maps. Matplotlib supports all of these forms.
Common Output Types
Python analysis usually produces a few standard outputs. These include cleaned tables, summary statistics, pivot style reports, exported CSV files, and charts for presentations or dashboards. Because pandas and Matplotlib are designed for data work, they fit this reporting style very well.
For complex datasets, the best output is often a combination of numbers and visuals. Tables show exact values. Charts show pattern and movement. Together they give a clearer picture than either format alone. This is why Python is such a common choice for practical analysis work.